Speeding Up Biotech R&D With an AI Data Strategy
Learn how biotech teams speed up R&D with an AI data strategy: where AI helps, why projects stall, six questions to ask and a practical way to start.
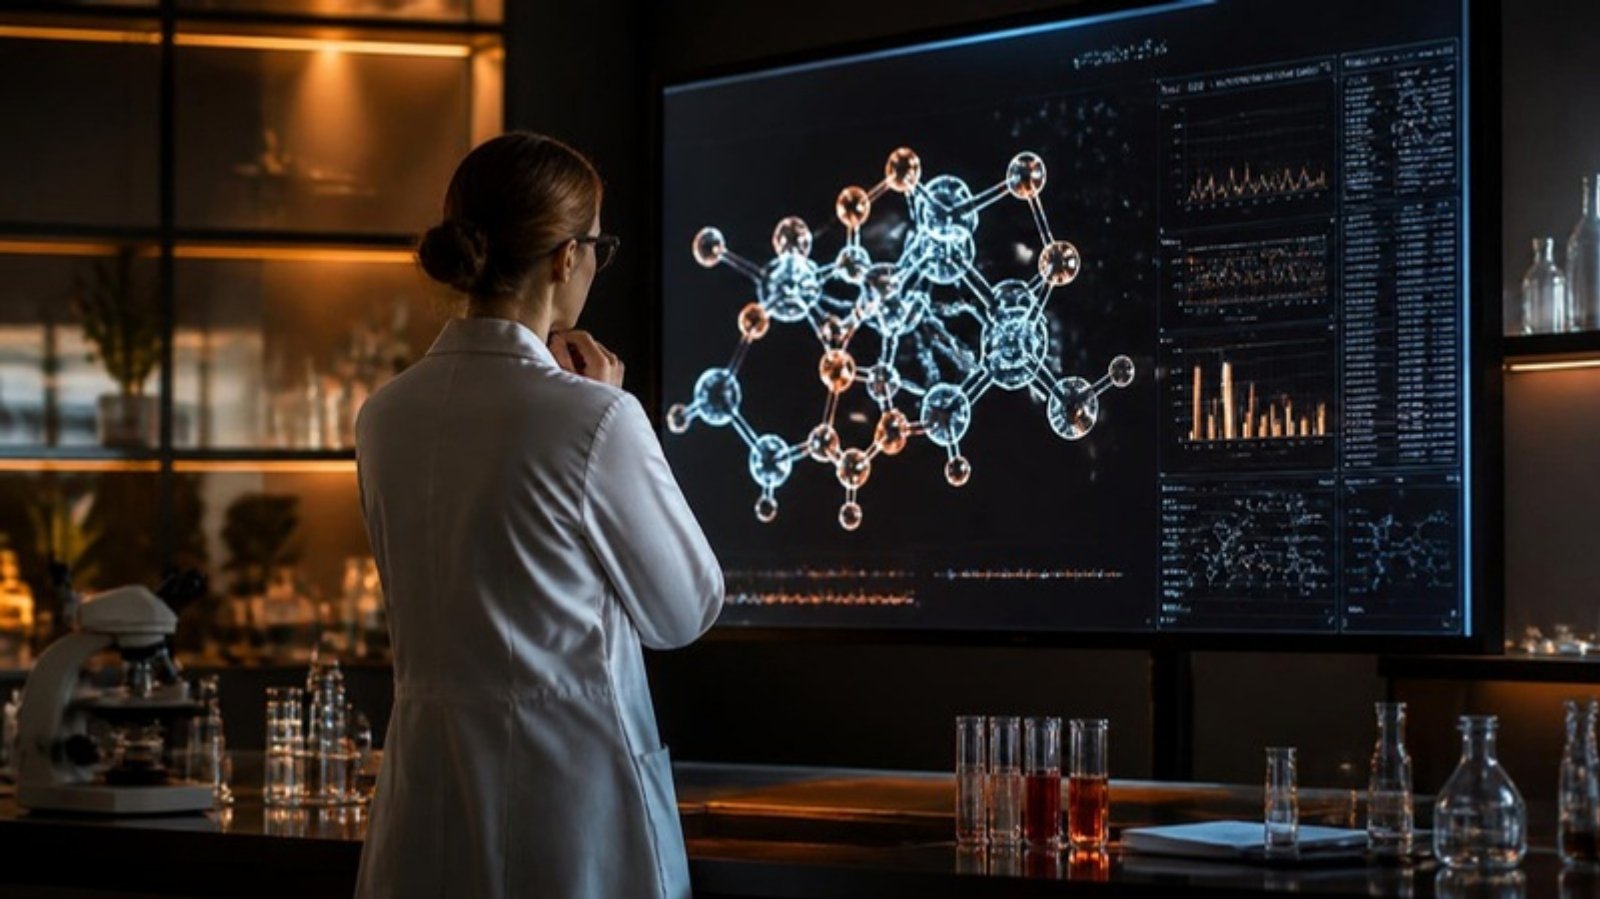
Biotech R&D teams are under constant pressure to move faster: shorter discovery cycles, leaner budgets and more data than any team can review by hand. AI can help speed up biotech R&D, but only when it runs on an AI data strategy that makes research, clinical and operational data connected, governed and ready to use.
Picture a biotech company where every team works from the same trusted data. Discovery scientists use AI to screen and refine candidate molecules. Translational teams test hypotheses against connected research and clinical evidence. Clinical operations plan studies and summarize findings in hours instead of weeks. None of this starts with the model. It starts with the data foundation underneath it.
How AI is speeding up biotech R&D
Across drug discovery and development, three AI applications are moving from experiment to everyday practice:
- Faster candidate design. Models that predict protein structure, chemical properties and how molecules bind to their targets help scientists prioritize the most promising candidates before committing lab time and budget.
- Synthetic data for secondary research. Statistically realistic synthetic datasets let teams explore hypotheses and validate analyses without exposing sensitive patient information.
- Summarizing scientific and clinical text. Language models condense large volumes of literature, protocols and study documentation into reviewable summaries, giving experts more time for judgment and less for reading.
Each of these depends on the same thing: large volumes of high-quality, well-described R&D data that teams are allowed to use. That's why research-focused AI, such as an AI agent for literature synthesis and evidence review, works best on top of a governed data foundation.
Why AI initiatives in R&D stall
Enthusiasm for AI in life sciences is high, but results are uneven. By some estimates cited in research from RAND, more than 80% of AI projects fail to deliver. The reasons are rarely about the model itself:
- Data quality and governance gaps. Data is scattered across instruments, lab systems, partners and spreadsheets, with inconsistent definitions and unclear ownership.
- No clear link to business value. Projects start without agreed success measures, so it's hard to prove impact or secure the next round of investment.
- Rising cost and complexity. Specialized infrastructure, scarce skills and integration with existing systems add up quickly.
- Security and compliance burden. Sensitive clinical and genomic data must meet strict privacy and regulatory expectations at every step.
- Legacy infrastructure. Older systems often can't share data easily, scale on demand or meet modern security standards.
Six questions to ask before investing in AI for R&D
Before committing to an AI initiative, R&D and data leaders should be able to answer:
- How confident are we in the quality and governance of the data this will rely on?
- Does the initiative fit our scientific priorities and our broader data strategy?
- What measures will define success, and how often will we review return on investment?
- How quickly can we expect results our scientists will actually use?
- What is the full cost of ownership, including maintenance, training and upgrades?
- Can the approach adapt as our programs, partners and technology evolve?
If several of these are hard to answer, the right first step is usually the data foundation, not the model.
What an AI-ready data strategy for biotech looks like
A modern data strategy gives AI something reliable to work with. In practice, it brings together six core capabilities.
Connected, multimodal research data
Research, clinical, genomic, imaging and operational data are brought into one governed foundation with shared definitions, so teams stop reconciling sources and start analyzing them.
Interoperability across the R&D pipeline
Systems share data cleanly from discovery through clinical development, reducing hand-offs and the delays that come with them.
Capacity that scales with the science
Compute expands for demanding workloads, such as large-scale screening or model training, without slowing down everyday analysis for other teams.
Secure collaboration with partners
Teams can work with research partners, contract organizations and third-party data while keeping control over who sees what.
Data governance and privacy by design
Access controls, lineage and audit trails are built in from the start, so compliance becomes part of the workflow rather than an obstacle to it. Our data and AI services are built around this principle.
Transparent, manageable cost
Managed, usage-based services reduce the overhead of maintaining infrastructure and make total cost of ownership easier to predict.
How to start: a practical roadmap for biotech teams
Biotech teams don't need a multi-year transformation to see results. A focused approach works better:
- Pick one high-value workflow, such as literature synthesis, candidate prioritization or study feasibility, where faster answers would change decisions.
- Build the governed data foundation for that workflow, with the quality, access and traceability your scientists and regulators expect.
- Put AI into the workflow with human review, measure the impact against the success criteria you agreed up front, then expand to the next use case.
See how this approach applies across discovery, translational research and clinical development on our biotechnology page.
Frequently asked questions
What is an AI data strategy in biotech R&D?
An AI data strategy is a plan for collecting, connecting, governing and securing research, clinical and operational data so it can be used reliably by analytics and AI. It covers data quality, shared definitions, access controls and how success will be measured.
How does AI speed up drug discovery?
AI helps scientists predict molecular properties and binding, prioritize candidates earlier, generate synthetic data for secondary analysis and summarize large volumes of literature and clinical documents, which reduces time spent on manual review and low-value experiments.
Why do AI projects in life sciences fail?
Most AI projects fail because of poor data quality, weak governance, unclear business goals, rising costs and integration challenges with legacy systems, rather than because of the AI models themselves.
Where should a biotech company start with AI?
Start with one high-value R&D workflow, build a governed data foundation for it, add AI with human review and measure results against agreed success criteria before expanding to other use cases.
Key takeaway
AI can speed up biotech R&D, but only when it's built on data that is connected, trusted and well governed. Organizations that invest in that foundation first are the ones that move from pilots to programs, and from scientific questions to development decisions, faster.
Put this into practice with our team
Share what you are working on and we will show how governed data and AI can move your programs forward.
Email marketing@kasmoglobal.com